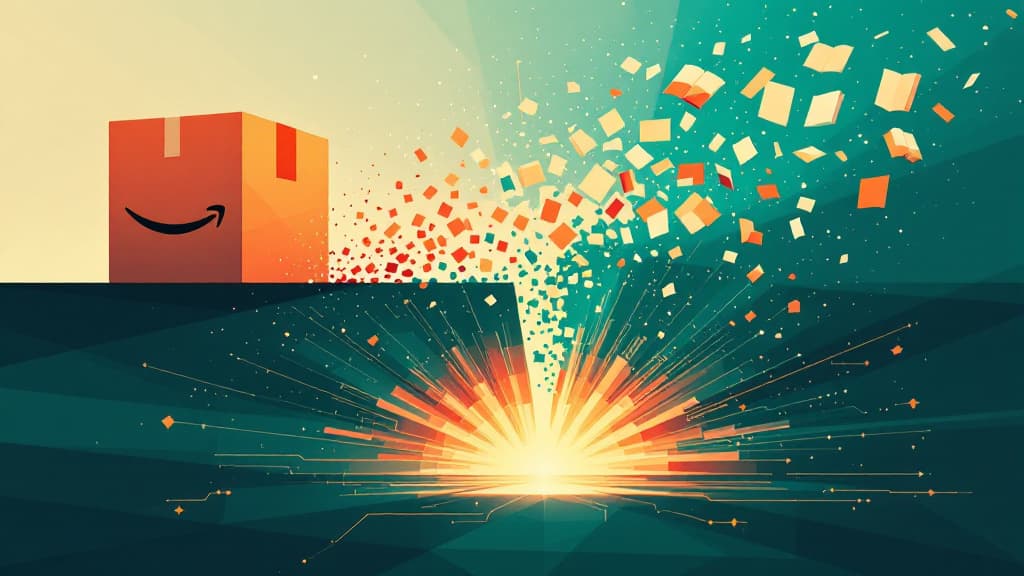
Amazon is reportedly purchasing and physically destroying rare, out-of-print books in order to digitize their contents for use in AI training datasets. The company, which built its early business selling books online, is now acquiring hard-to-find texts that have never been digitized and converting them into training material for large language models.
The Details
The rationale is straightforward: LLMs have largely exhausted the supply of text available on the open internet, making rare physical books an increasingly valuable source of novel training data.
Key points from the reporting:
- Rare and out-of-print books represent content that AI models have never encountered, making them disproportionately valuable for improving model quality
- Amazon is physically destroying these books as part of the digitization process, meaning the original copies are lost permanently
- The practice raises significant concerns from archivists, librarians, and preservation advocates who argue these texts have cultural and historical value that cannot be replicated
- This is part of a broader industry trend; AI developers are aggressively seeking new data sources as easily accessible online content becomes insufficient
The destruction of irreplaceable physical texts to feed AI pipelines is drawing criticism well beyond the preservation community. There are also unresolved questions about copyright, author compensation, and whether rightsholders have consented to this use of their work.
Why This Matters for Service Providers
This story is a signal, not just a headline. The AI models your clients are using, and the ones you may be reselling or building services on top of, are only as good as the data they were trained on. As major players race to acquire novel training data through increasingly aggressive means, the quality and legal standing of that data is becoming a competitive and compliance issue.
For MSPs and telecom resellers deploying AI-powered tools, understanding the upstream data provenance of the models you rely on matters. Regulatory scrutiny around AI training data is increasing, and compliance obligations are already evolving rapidly in adjacent areas of the industry.
The practical takeaway: when evaluating AI vendors, start asking harder questions about model training practices. Your enterprise clients, particularly those in regulated industries, may soon be asking those questions of you.
Looking Ahead
Watch for potential legislative or legal action targeting AI training data acquisition practices, especially in the EU where existing frameworks are more aggressive. If you are advising clients on AI adoption, this is a good time to build vendor due diligence on data sourcing into your standard evaluation process.
For the full story, read the original article on TechCrunch AI.